The shelf life of LLM findings: retesting 50 claims on newer models
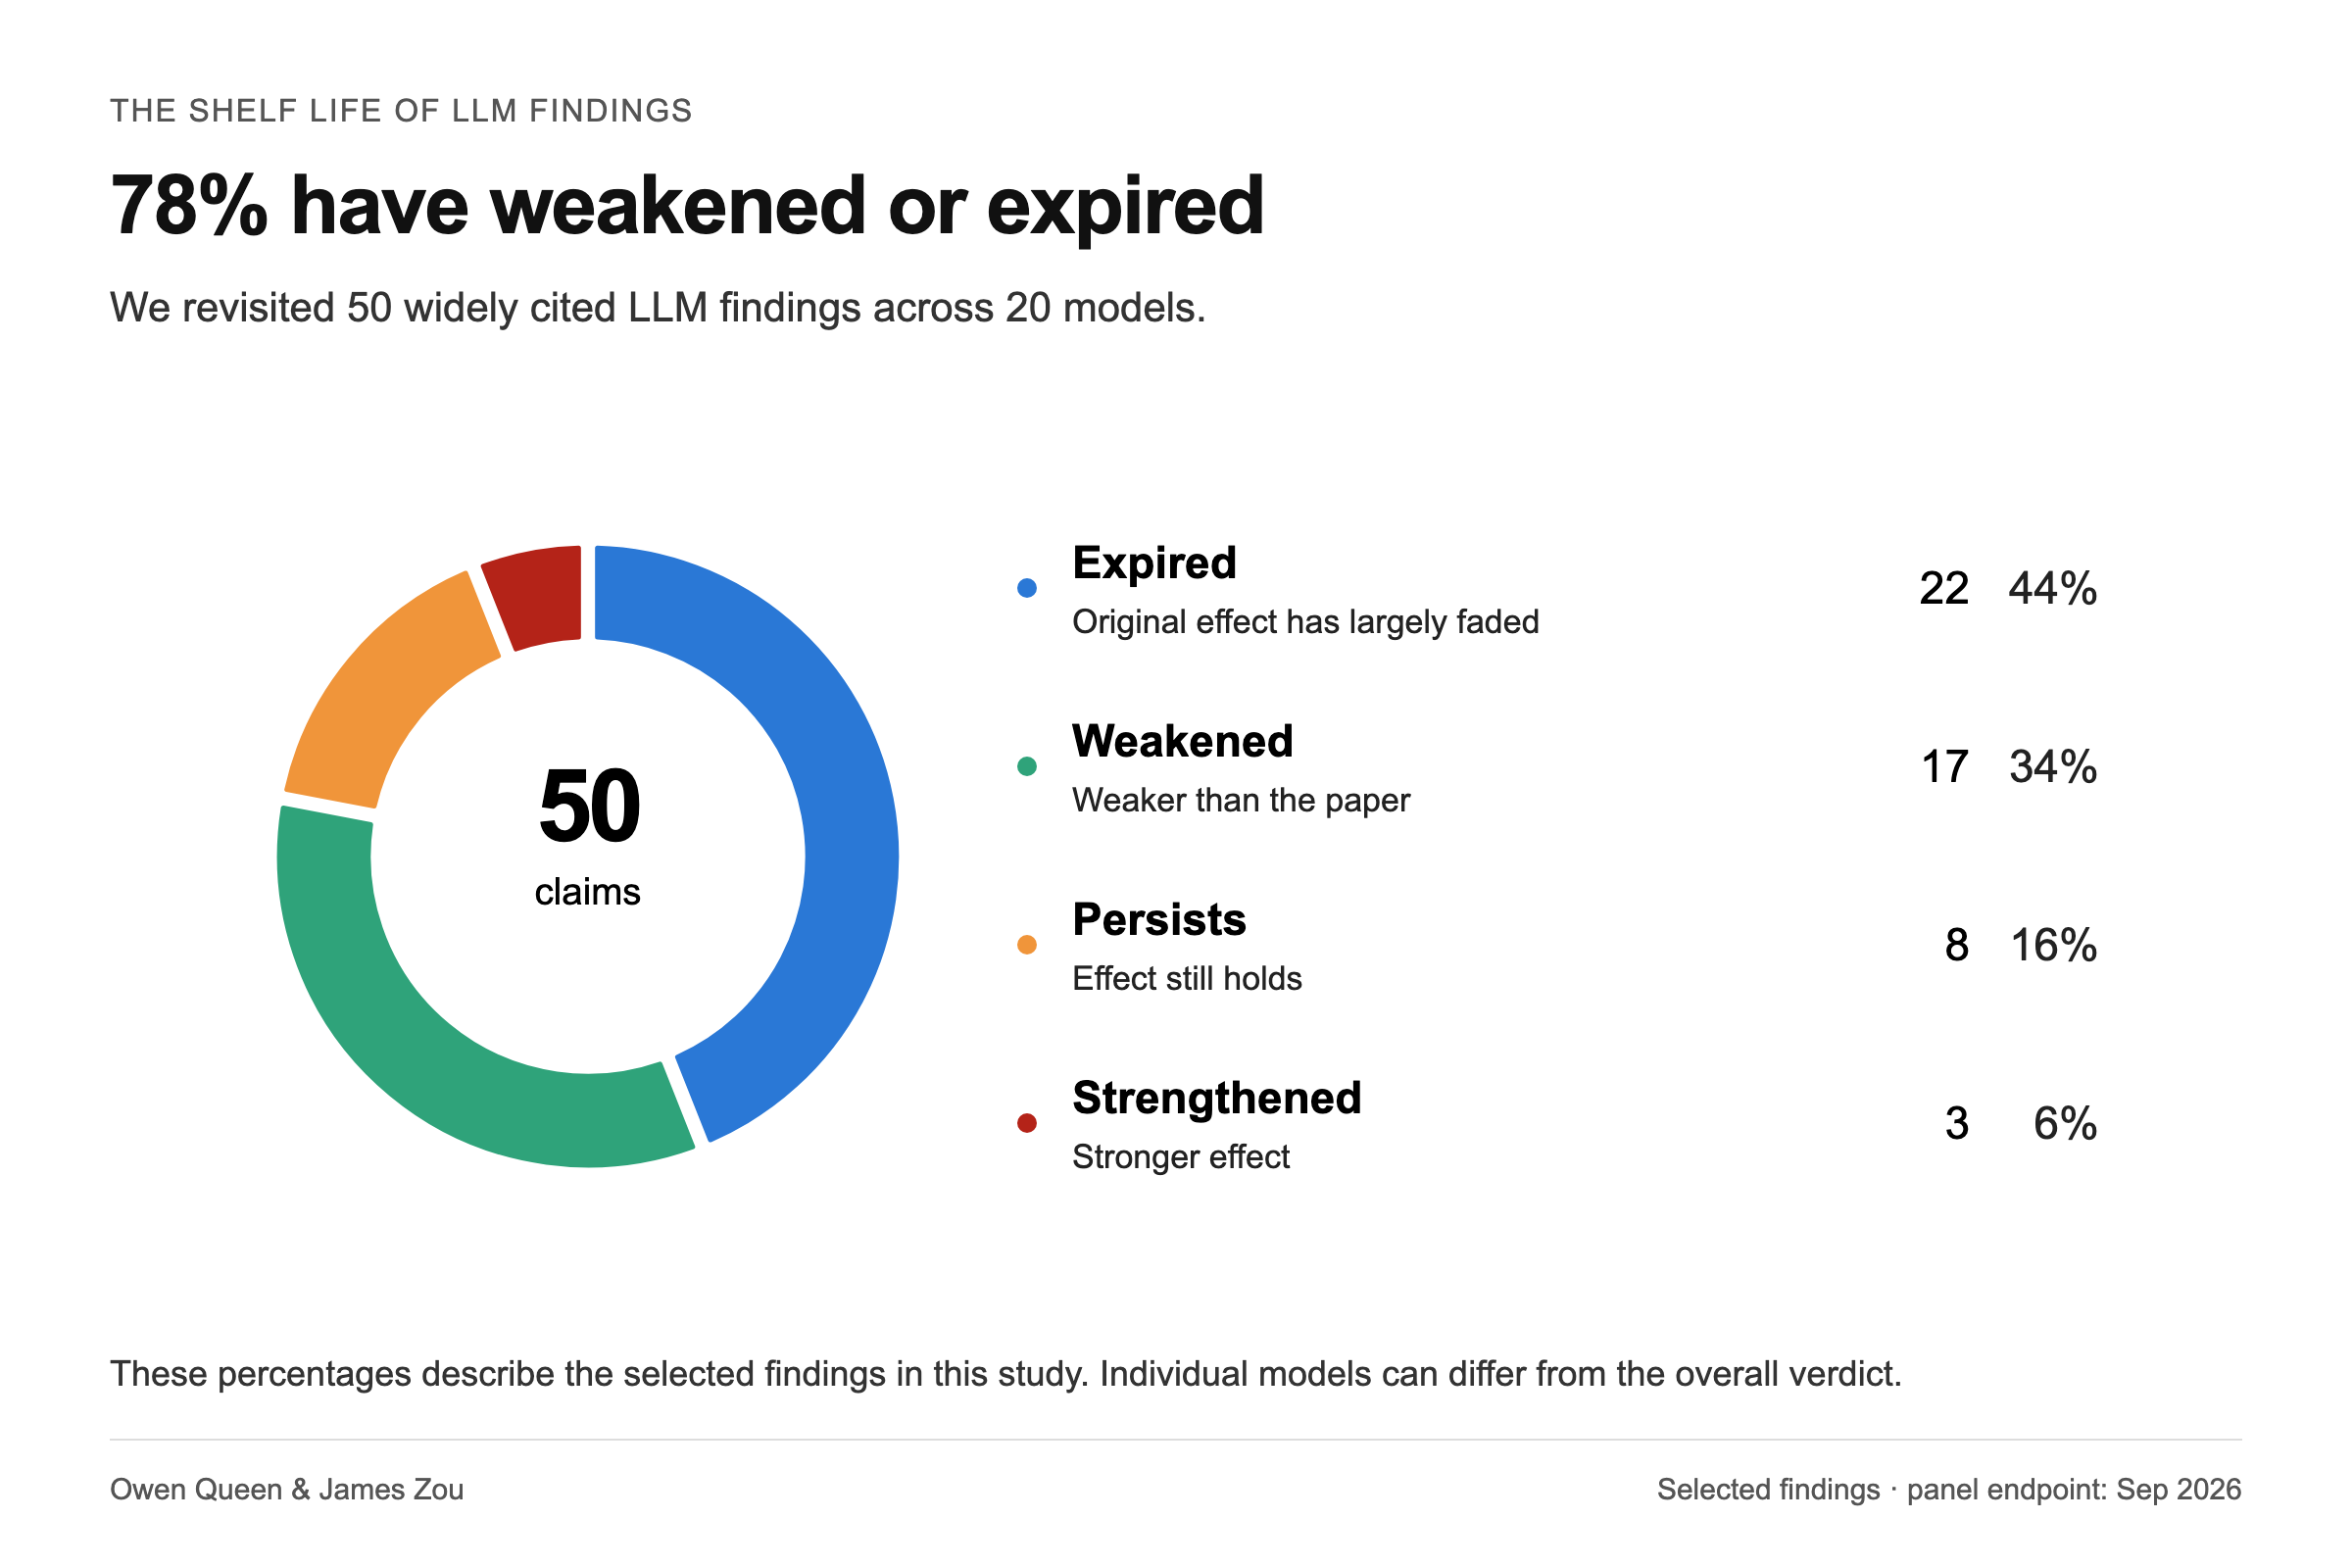
An AI failure measured in 2023 may describe today's models poorly. Owen Queen and James Zou revisited 50 selected findings across 20 models, covering reasoning, hallucination and model preferences.
Their November 2 study classifies 22 findings as largely faded and 17 as weakened. Some tendencies grew stronger, including judges favouring their own answers and praise following a user's stated preference.
“Expired” is a study category, not proof that a problem vanished from every model. The claims and models were hand-picked, and some original models required substitutes. Code and derived results are available, but the underlying saved model outputs are not included. Explore the interactive claim cards before turning the headline into a general verdict about AI.